Official Paper

GATE CS 2016 Official Paper: Shift 2 (Previous Year Paper)

65 questions · 180 minutes · with answers · free

General Aptitude (10 questions)

1

The man who is now Municipal Commissioner worked as ____________________.

  1. ((a))

    the security guard at a university

  2. ((b))

    a security guard at the university

  3. ((c))

    a security guard at university

  4. ((d))

    the security guard at the university

Show Answer
Answer: ((b))

a security guard at the university

The sentence is talking about the Municipal Commissioner’s previous profession. There cannot be only one security guard at the University. Thus, the indefinite article should precede the security guard. Since the location where he used to work is specific, definite article ‘the’ needs to precede it. Hence the correct option satisfying this criteria is option 2.
2

Nobody knows how the Indian cricket team is going to cope with the difficult and seamer-friendly wickets in Australia. Choose the option which is closest in meaning to the underlined phrase in the above sentence.

  1. ((a))

    put up with

  2. ((b))

    put in with

  3. ((c))

    put down to

  4. ((d))

    put up against

Show Answer
Answer: ((a))

put up with

The sentence is speaking about the problem that the Indian cricket team will face in Australia. Thus, the best phrase to replace is ‘put up with’.

3

Find the odd one in the following group of words. mock, deride, praise, jeer

  1. ((a))

    mock

  2. ((b))

    deride

  3. ((c))

    praise

  4. ((d))

    jeer

Show Answer
Answer: ((c))

praise

The correct answer is praise

Key Points

  • The words ‘deride’, ‘mock’, ‘jeer’ are synonyms that are negative words meaning to ridicule or make fun of.
  • The other word ‘praise’ is a positive word that means to ‘express admiration’. Hence it is the odd one out.
4

Pick the odd one from the following options.

  1. ((a))

    CADBE

  2. ((b))

    JHKIL

  3. ((c))

    XVYWZ

  4. ((d))

    ONPMQ

Show Answer
Answer: ((d))

ONPMQ

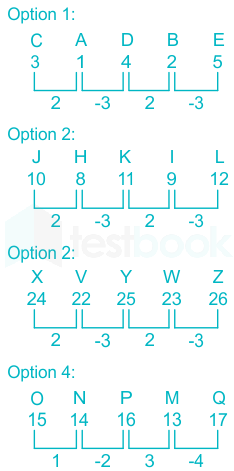
Option D is generating different pattern and hence it is the odd man out

5

In a quadratic function, the value of the product of the roots (α, β) is 4. Find the value of

αn+βnan+βn\frac{{{\alpha ^n} + {\beta ^n}}}{{{a^{ - n}} + {\beta ^{ - n}}}}

  1. ((a))

    n4{n^4}

  2. ((b))

    4n{4^n}

  3. ((c))

    22n1{2^{2n - 1}}

  4. ((d))

    4n1{4^{n - 1}}

Show Answer
Answer: ((b))

4n{4^n}

αn+βnαn+βn=αn+βn1αn+1βn =(αnβn)(αn+βn)αn+βn =(αβ)n=4n\begin{array}{l} \frac{{{\alpha ^n} + {\beta ^n}}}{{{\alpha ^{ - n}} + {\beta ^{ - n}}}} = \frac{{{\alpha ^n} + {\beta ^n}}}{{\frac{1}{{{\alpha ^n}}} + \frac{1}{{{\beta ^n}}}}}\ = \frac{{\left( {{\alpha ^n}{\beta ^n}} \right)\left( {{\alpha ^n} + {\beta ^n}} \right)}}{{{\alpha ^n} + {\beta ^n}}}\ = {\left( {\alpha \beta } \right)^n} = {4^n} \end{array}

6

Among 150 faculty members in an institute, 55 are connected with each other through Facebook and 85 are connected through WhatsApp. 30 faculty members do not have Facebook or WhatsApp accounts. The number of faculty members connected only through Facebook accounts is ______________.

  1. ((a))

    35

  2. ((b))

    45

  3. ((c))

    65

  4. ((d))

    90

Show Answer
Answer: ((a))

35

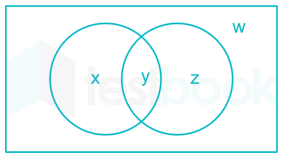
No of members only on Facebook =x= x

No of members only on Whatsapp =z= z

No. of members on both =y= y

No of members on neither =w= w

x+y+z+w=150 x+y=55 y+z=85,;w=30 x+y+z=120 x=12085; x=35\begin{array}{l} x + y + z + w = 150\ x + y = 55\ y + z = 85,;w = 30\ x + y + z = 120\ x = 120-85;\ x = 35 \end{array}

7

Computers were invented for performing only high-end useful computations. However, it is no understatement that they have taken over our world today. The internet, for example, is ubiquitous. Many believe that the internet itself is an unintended consequence of the original invention. With the advent of mobile computing on our phones, a whole new dimension is now enabled. One is left wondering if all these developments are good or, more importantly, required.

Which of the statement(s) below is/are logically valid and can be inferred from the above paragraph?

(i) The author believes that computers are not good for us.

(ii) Mobile computers and the internet are both intended inventions

  1. ((a))

    (i) only 

  2. ((b))

    (ii) only

  3. ((c))

    both (i) and (ii)

  4. ((d))

    neither (i) nor (ii)

Show Answer
Answer: ((d))

neither (i) nor (ii)

The passage states how computers have taken over the world today. The last line of the passage helps us infer that though the author understands how the new developments like computers have helped us, he is dubious as to whether these developments are actually beneficial or required.

The first inference does not hold.

The second inference does not hold because the passage clearly states that many people feel that the internet is an unintended invention.

8

All hill-stations have a lake. Ooty has two lakes.

Which of the statement(s) below is/are logically valid and can be inferred from the above sentences?

(i) Ooty is not a hill-station.

(ii) No hill-station can have more than one lake.

  1. ((a))

    (i) only

  2. ((b))

    (ii) only

  3. ((c))

    both (i) and (ii)

  4. ((d))

    neither (i) nor (ii)

Show Answer
Answer: ((d))

neither (i) nor (ii)

Let us look at the inferences one by one.

Since all hill stations have lakes and Ooty has two lakes, then Ooty must be a hill station.

The second inference does not follow because there can be no fixed rule as to how many lakes must a hill station have.

Thus none of the inferences follow.

9

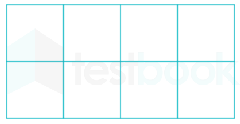
In a 2 × 4 rectangle grid shown below, each cell is a rectangle. How many rectangles can be observed in the grid?

  1. ((a))

    21

  2. ((b))

    27

  3. ((c))

    30

  4. ((d))

    36

Show Answer
Answer: ((c))

30

Data:

number of rows = n = 2

number of columns = m = 4

Formula:

number;of;rectangles=(n×(n+1)2)×(m×(m+1)2)number ;of ;rectangles =( \frac{n×(n+1)}{2})×(\frac{m×(m+1)}{2} )

Calculation:

number;of;rectangles=(2×(2+1)2)×(4×(4+1)2)number ;of ;rectangles =( \frac{2×(2+1)}{2})×(\frac{4×(4+1)}{2} )

number of rectangles = 3 × 10 = 30

10

Choose the correct expression for f(x) given in the graph.

  1. ((a))

    f(x)=1x1f\left( x \right) = 1 - \left| {x - 1} \right|

  2. ((b))

    f(x)=1+x1f\left( x \right) = 1 + \left| {x - 1} \right|

  3. ((c))

    f(x)=2x1f\left( x \right) = 2 - \left| {x - 1} \right|

  4. ((d))

    f(x)=2+x1f\left( x \right) = 2 + \left| {x - 1} \right|

Show Answer
Answer: ((c))

f(x)=2x1f\left( x \right) = 2 - \left| {x - 1} \right|

Putting the values shown is graph, option (C) matches.

Computer Science and Information Technology (55 questions)

11

Consider the following expressions:

(i) false

(ii) Q

(iii) true

(iv) P ∨ Q

(v) ¬ Q ∨ P

The number of expressions given above that are logically implied by P ∧ (P ⇒ Q) is ________

12

Let f(x) be a polynomial and g(x) = f’(x) be its derivative. If the degree of (f(x) + f(– x)) is 10, then the degree of (g(x) – g(– x)) is _______.

13

The minimum number of colours that is sufficient to vertex-colour any planar graph is_______. 

14

Consider the systems, each consisting of m linear equations in n variables.

I. If m < n, then all such systems have a solution

II. If m > n, then none of these systems has a solution

III. If m = n, then there exists a system which has a solution

Which one of the following is CORRECT?

  1. ((a))

    I, II and III are true

  2. ((b))

    Only II and III are true

  3. ((c))

    Only III is true

  4. ((d))

    None of them is true

Show Answer
Answer: ((c))

Only III is true

Statement I:

If m < n, then all such systems have a solution [incorrect]

Let us suppose m = 2, n = 3

x + y + z = 3

x + y + z = 5

here, this will not give any solution. Because, when we have 2 equations with 3 variables, we can’t find the solution for this.

Statement II:

If m > n, then none of these systems has a solution [incorrect]

Consider, m = 3, n = 2

System of equation will be like:

x + 2y = 2

x + y = 1

2x + 5y = 5

But here we can easily find the value of x and y.

Statement III:

If m = n, then there exists a system which has a solution [Correct]

Consider m = 2, n = 2

System of equation will be like:

x + 2y = 3

2x + 4y = 4

Here, x and y can be calculated. These systems of equations have a solution.

15

Suppose that a shop has an equal number of LED bulbs of two different types. The probability of an LED bulb lasting more than 100 hours given that it is of Type 1 is 0.7 and given that it is of Type 2 is 0.4. The probability that an LED bulb chosen uniformly at random lasts more than 100 hours is_______. 

16

Suppose that the eigenvalues of matrix A are 1, 2, 4. The determinant of (A-1)T is______.

17

Consider an eight-bit ripple-carry adder for computing the sum of A and B, where A and B are integers represented in 2’s complement form. If the decimal value of A is one, the decimal value of B that leads to the longest latency for the sum to stabilize is _______.

18

Let, x1 ⊕ x2 ⊕ x3 ⊕ x4 = 0 where x1, x2, x3, x4 are Boolean variables, and ⊕ is the XOR operator.

Which one of the following must always is TRUE?

  1. ((a))

    x1x2x3x4 = 0

  2. ((b))

    x1x3 + x2 = 0

  3. ((c))

    1 ⊕ x̅3 = x̅2 ⊕ x̅4

  4. ((d))

    x1 + x2 + x3 + x4 = 0

Show Answer
Answer: ((c))

1 ⊕ x̅3 = x̅2 ⊕ x̅4

Concept:

XOR gate is a gate that gives a true output when the number of true inputs is odd.

Explanation:

Given, x1 ⊕ x2 ⊕ x3 ⊕ x4 = 0

Where, x1, x2, x3, x4 are Boolean variables, and ⊕ is the XOR operator

Consider x1 = 1, x2 =1, x3 =1 and x4= 1

1 ⊕ 1 ⊕ 1 ⊕ 1 = 0

Now, consider all the options one by one.

  1. x1x2x3x4 = 0 [Incorrect]

Here, put the value of x1,x2, x3, x4 as 1

So, 1.1.1.1 = 1

  1. x1x3 + x2 = 0 [Incorrect]

1.1 + 1 =1

  1. 1 ⊕ x̅3 = x̅2 ⊕ x̅4 [Correct]

Here, x̅1 = x̅3 = x̅2 = x̅4 = 0,

So, 0 ⊕ 0 = 0 ⊕ 0,

0 = 0

  1. x1 + x2 + x3 + x4 = 0 [Incorrect]

As, 1+1+1+1 = 1

19

Let X be the number of distinct 16-bit integers in 2’s complement representation. Let Y be the number of distinct 16-bit integers in sign magnitude representation.

Then X – Y is _______.

20

A processor has 40 distinct instructions and 24 general purpose registers. A 32-bit instruction word has an opcode, two register operands and am immediate operand. The number of bits available for the immediate operand field is ______. 

21

Breadth First Search (BFS) is started on a binary tree beginning from the root vertex. There is a vertex t at a distance 4 from the root. If t is the n-th vertex in this BFS traversal, then the maximum possible value of n is _______.

22

The value printed by the following program is _______.

void f (int* p, int m) {

m = m + 5;

*p = *p + m;

return;

}

void main () {

        int i=5, j=10;

        f (&i, j);

        printf (‘’%d’’, i+j);

}

23

Assume that the algorithms considered here sort the input sequences in ascending order. If the input is already in ascending order, which of the following are TRUE?

I. Quicksort runs in Θ (n2) time

II. Bubblesort runs in Θ (n2) time

III. Mergesort runs in Θ (n) time

IV. Insertion sort runs in Θ (n) time

  1. ((a))

    I and II only

  2. ((b))

    I and III only

  3. ((c))

    II and IV only

  4. ((d))

    I and IV only

Show Answer
Answer: ((d))

I and IV only

Input is already in ascending order, means it is the worst-case situation.

Option 1:

Quicksort runs in Θ (n2) time

In quick sort worst case, first or last element is selected at the pivot element.

For a quicksort, in worst case recurrence relation will become T(n) = T(n-1) + T (1) + n

Which gives T(n) = Θ (n2)

So, it is correct.

Option 2:

Bubble sort runs in Θ (n2) time

If array is already sorted in ascending order, then at that time there will be no swap after the completion of inner for loop of bubble sort. In this way, bubble sort will take Θ (n) time complexity.

Option 3:

Merge sort runs in Θ (n) time

Merge sort uses the divide and conquer policy to sort the elements. As elements are already sorted in ascending order. Recurrence relation for merge sort; T(n) = 2 T (n/2) + n

This will give Θ (nlogn) time complexity.                        

Option 4:

Insertion sort runs in Θ (n) time

When a new element which is greater than all the elements of the array is added, then there will be no swap but only a single comparison. In n -1 swaps, only 0 swaps and n-1 comparisons are there.

Total time complexity in this case will be Θ (n).

24

The Floyd-Warshall algorithm for all-pair shortest paths computation is based on

  1. ((a))

    Greedy paradigm.

  2. ((b))

    Divide-and-Conquer paradigm.

  3. ((c))

    Dynamic Programming paradigm.

  4. ((d))

    neither Greedy nor Divide-and-Conquer nor Dynamic Programming paradigm.

Show Answer
Answer: ((c))

Dynamic Programming paradigm.

Floyd Warshall algorithm is based on dynamic programming paradigm.

It finds the all pair shortest paths:

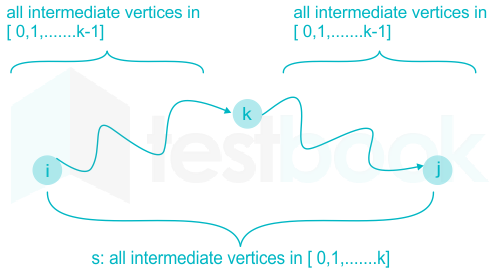
Consider for every pair (i, j), there are two possible cases:

  1. k is not an intermediate vertex in shortest path from i to j. We keep the value of dist[i][j] as it is.

  2. k is an intermediate vertex in shortest path from i to j. We update the value of dist[i][j] as dist[i][j] + dist[.k][j]

This diagram shows it:

While using dynamic programming paradigm, we computer all pair shortest path time complexity is O(V3).

25

N items are stored in a sorted doubly linked list. For a delete operation, a pointer is provided to the record to be deleted. For a decrease-key operation, a pointer is provided to the record on which the operation is to be performed.

An algorithm performs the following operations on the list in this order: Θ(N) delete, O(log N) insert, O(log N) find, and Θ(N) decrease-key. What is the time complexity of all these operations put together?

  1. ((a))

    O(log2N)

  2. ((b))

    O(N)

  3. ((c))

    O(N2)

  4. ((d))

    Θ (N2log N)

Show Answer
Answer: ((c))

O(N2)

Here, it is given that pointer is provided to the record on which the decrease key operation is to be performed. So, time complexity of decrease key operation is Θ (1)

For insert – Θ (N), we need to insert the element at the end of the sorted list.

For delete – Θ (1) time is needed, as pointer is directly given

For decrease key – Θ (N), because after decreasing the key value, all the elements must be sorted again.

Now combining all the operations together:

For delete = Θ (N)* Θ (1) [because Θ(N) delete operations ]

For insert = Θ (log N)*Θ (N) [because Θ(logN insert operations are given)]

For find = Θ (log N)*Θ (N)

For decrease-key = Θ (N)* Θ (N)

So, overall complexity = Θ (N)* Θ (1 ) + Θ (logN)* Θ (N) + Θ (logN)* Θ (N)+ Θ (N)* Θ (N)

Time complexity of all these operations put together = Θ (N2)

26

The number of states in the minimum sized DFA that accepts the language defined by the regular expression 

(0 + 1)(0 + 1)(0 + 1)

is ______.

27

Language L1 is defined by the grammar: S1 → aS1b|ϵ

Language L2 is defined by the grammar: S2 → abS2

Consider the following statements:

P: L1 is regular

Q: L2 is regular

Which one of the following is TRUE?

  1. ((a))

    Both P and Q are true

  2. ((b))

    P is true and Q is false

  3. ((c))

    P is false and Q is true

  4. ((d))

    Both P and Q are false

Show Answer
Answer: ((c))

P is false and Q is true

Suppose grammar G1:

S1 → aS1b|ϵ

It generates language in which number of a’s are equal to number of b’s and all a’s are followed by b’s

L1 = { an bn | n ≥ 0}.

It is deterministic context free language. Extra memory is required for this. So, it can’t be accepted by finite state automata. L1 is not a regular language.

Now, another grammar let G2: S2 → abS2

This grammar also generates language in which number of a’s are equal to number of b’s. But it generates language L2 = { (ab)n | n ≥ 0 }

Regular expression for this = (ab)*

It doesn’t require any extra memory to remember the last string. It can be accepted by finite state automata. So, L2 is regular.

28

Consider the following types of languages: L1: Regular, L2: Context-free, L3 : Recursive, L4 : Recursively enumerable. Which of the following is/are TRUE?

I. L̅3 ∪ L4 is recursively enumerable

II. L̅2 ∪ L3 is recursive

III. L1* ∩ L2 is context-free 

IV. L1 ∪ L̅2 is context-free

  1. ((a))

    I only

  2. ((b))

    I and III only

  3. ((c))

    I and IV only

  4. ((d))

    I, II and III only

Show Answer
Answer: ((d))

I, II and III only

L1: Regular

L2: Context-free

L3: Recursive

L4: Recursively enumerable

Statement I: TRUE

 L̅3 ∪ L4 is recursively enumerable

As L3 is recursive language and complement of a recursive language is also recursive.

L4 is recursive enumerable. So, L̅3 ∪ L4 is recursive enumerable.

Statement II: TRUE

II. L̅2 ∪ L3 is recursive

L2 is context free language. Context free languages are not closed under complementation. Complement of a context free language is context sensitive also recursive. L3 is recursive.

So, union of two recursive languages is recursive.

Statement III: TRUE

III. L1* ∩ L2 is context-free 

Kleen closure of regular language is regular. Intersection of a regular language and context free language is context free.

Example:

Regular language = \(L^_1 = (a + b)^\)

L2 = an bn

The intersection of L1L2=anbnL^*_1 \cap L_2 = a^nb^n is a context-free language 

Statement IV: FALSE

L1 ∪ L̅2 is context-free

Complement of L2 is not context free.  L1 ∪ L̅2 may or may not be context free.

Therefore, the statement I, II and III are correct.

29

Match the following:

(P)Lexical analysis(i)Leftmost derivation
(Q)Top down parsing(ii)Type checking
(R)Semantic analysis(iii)Regular expressions
(S)Runtime environments(iv)Activation records
  1. ((a))

    P – i, Q – ii, R – iv, S - iii

  2. ((b))

    P – iii, Q – i, R – ii, S - iv

  3. ((c))

    P – ii, Q – iii, R – I, S - iv

  4. ((d))

    P – iv, Q – I, R – ii, S - iii

Show Answer
Answer: ((b))

P – iii, Q – i, R – ii, S - iv

Lexical analysis: Lexical analysis is the first phase of a compiler. It takes the modified source code from language pre-processors that are written in the form of sentences.  Lexical analyser breaks these syntaxes into a series of tokens. Lexical analysis uses regular expression to recognize identifiers.

Top down parsing: Top down parsing technique parses the input by starts constructing a parse tree from the root node moving down to the leaf nodes. Top down parser uses the left most derivation to generate the string.

Semantic analysis: Semantic analysis is the task of ensuring that declarations and statements of a program are semantically correct. For this, it uses type casting.

Run time environments: Run time environment is a state of the target machine, which may include software libraries, environment variables etc. to provide services to the processes running in the system. Activation records of a function are loaded into stack at runtime.

30

In which one of the following page replacement algorithms it is possible for the page fault rate to increase even when the number of allocated frames increases? 

  1. ((a))

    LRU (Least Recently Used)

  2. ((b))

    OPT (Optimal Page Replacement)

  3. ((c))

    MRU (Most Recently Used)

  4. ((d))

    FIFO (First In First Out)

Show Answer
Answer: ((d))

FIFO (First In First Out)

Concept:

Belady’s anomaly is the phenomenon in which increasing the number of page frame results in  increase in the number of page faults.

Explanation:

FIFO replacement algorithm results in page faults by increasing the number of page frames.

Consider the example:

Frame = 3

String = 0 1 5 3 0 1 4 0 1 5 3 4

REQUEST015301401534
Frame 35551111133
Frame 211100000555
Frame 1000333444444
Miss/HitMissMissMissMissMissMissMissHitHitMissMissHit


Number of page faults = 9

Take number of frames = 4

REQUEST015301401534
Frame 4333333555
Frame 35555551111
Frame 211111100004
Frame 1000000044433
Miss/HitMissMissMissMissHitHitMissMissMissMissMissMiss
<br>

Number of page faults = 10

31

B+ Trees are considered BALANCED because 

  1. ((a))

    the lengths of the paths from the root to all leaf nodes are all equal.

  2. ((b))

    the lengths of the paths from the root to all leaf nodes differ from each other by at most 1.

  3. ((c))

    the number of children of any two non-leaf sibling nodes differ by at most 1.

  4. ((d))

    the number of records in any two leaf nodes differ by at most 1.

Show Answer
Answer: ((a))

the lengths of the paths from the root to all leaf nodes are all equal.

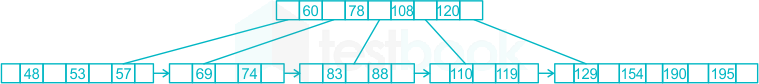
B+ Tree is an extension of B tree which allows efficient insertion, deletion and search operations.

In a B+ Tree, records (data) can only be stored on the leaf nodes while internal nodes can only store the key values. Leaf nodes of a B+ Tree are linked together in form of linked list to make the search operation efficient.

In a B+ Tree, all leaves are at the same level. In both B Tree and B+ Tree, length of root to leaf nodes is same. In B+ Tree, insertion is done in a way such that if we increase height of tree after insertion, we increase height from the root. While in BST, height of tree after insertion increased from leaf nodes.

Similarly, if we have to decrease the height of the tree after deletion, we move the root one level down.

So, this will make sure that depth of leaf nodes are same and B+ Tree are balanced trees.

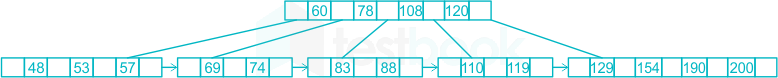
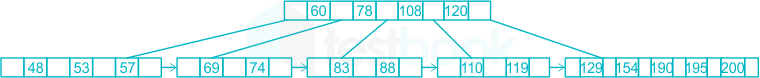
Insertion example:

Insert 195,


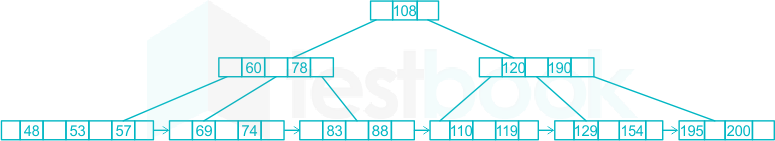
Final, B+ Tree will be:

Deletion example:

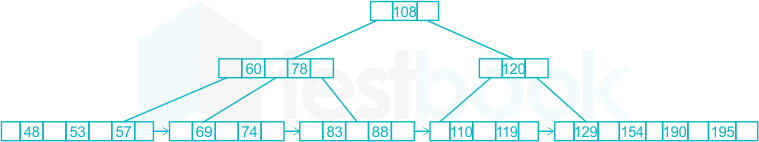
Delete 200 from above tree

Now, 120 is the single element violating the property of B+ tree so, merge it and height of tree will be decreased by 1.

32

Suppose a database schedule S involves transactions T1, …,Tn. Construct the precedence graph of S with vertices representing the transactions and edges representing the conflicts. If S is serializable, which one of the following orderings of the vertices of the precedence graph is guaranteed to yield a serial schedule?

  1. ((a))

    Topological order

  2. ((b))

    Depth-first order

  3. ((c))

    Breadth-first order

  4. ((d))

    Ascending order of transaction indices

Show Answer
Answer: ((a))

Topological order

Serial schedule is possible only when precedence graph doesn’t contain cycle. If precedence graph contains a cycle, it means schedule is not conflict serializable.

Breadth first search and Depth first search of a graph are possible even if graph contains cycle.

Topological sort in a graph will not work if graph contains a cycle.

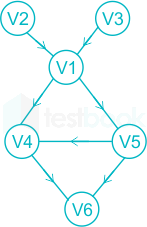
Consider a directed acyclic graph:

Here Two orders possible: V2, V3, V1, V4, V5, V6 OR V3, V2, V1, V4, V5, V6.

In case of ascending order of transaction indices, two non-conflicting schedules can occur simultaneously.

33

Anarkali digitally signs a message and sends it to Salim. Verification of the signature by Salim requires

  1. ((a))

    Anarkali’s public key.

  2. ((b))

    Salim’s public key.

  3. ((c))

    Salim’s private key.

  4. ((d))

    Anarkali’s private key.

Show Answer
Answer: ((a))

Anarkali’s public key.

Concept:

Digital signature is a cryptographic value that is calculated from the data and a secret key known only by the signer. In real world, the receiver of message needs assurance that the message belongs to the sender and he should not be able to repudiate the origination of that message.

In Digital signature:

Encryption is done by sender’s private key and decryption is done by sender’s public key.

Here, it is given that Anarkali digitally signs the message and sends it to the Salim. As, Anarkali signs the message with her private key and Salim (receiver ) uses the Anarkali’s public key to verify the signature.

34

In an Ethernet local area network, which one of the following statements is TRUE?

  1. ((a))

    A station stops to sense the channel once it starts transmitting a frame.

  2. ((b))

    The purpose of the jamming signal is to pad the frames that are smaller than the minimum frame size.

  3. ((c))

    A station continues to transmit the packet even after the collision is detected.

  4. ((d))

    The exponential back-off mechanism reduces the probability of collision on retransmissions.

Show Answer
Answer: ((d))

The exponential back-off mechanism reduces the probability of collision on retransmissions.

Ethernet is a way of connecting computers together in a local area network (LAN). Ethernet operates in two layers of OSI model, physical and data link layer. In order to handle the collision in Ethernet, access control mechanism used is CSMA/CD.

  1. A station stops to sense the channel once it starts transmitting a frame.

In Ethernet, a station need not stop sensing the channel once it starts transmitting a frame. So, it is false

  1. The purpose of the jamming signal is to pad the frames that are smaller than the minimum frame size.

Jamming signal in Ethernet is signal that carries 32-bit binary pattern sent by a data station to inform other stations of the collision. It is not true that the purpose of jamming signal is to pad the frames that are smaller than the minimum frame size.

  1. A station continues to transmit the packet even after the collision is detected. Once the collision has occurred, jam signal will be sent and after that station will stop transmitting the packet. So, it is incorrect.

  2. The exponential back-off mechanism reduces the probability of collision on retransmissions.

Exponential back off algorithm is used to space out repeated retransmissions of the same block of data to avoid network congestion. It is a collision resolution mechanism which is used in random access MAC protocols. So, it is correct.

35

Identify the correct sequence in which the following packets are transmitted on the network by a host when a browser requests a webpage from a remote server, assuming that the host has just been restarted. 

  1. ((a))

    HTTP GET request, DNS query, TCP SYN

  2. ((b))

    DNS query, HTTP GET request, TCP SYN

  3. ((c))

    DNS query, TCP SYN, HTTP GET request

  4. ((d))

    TCP SYN, DNS query, HTTP GET request

Show Answer
Answer: ((c))

DNS query, TCP SYN, HTTP GET request

During packet transmission, first step is to make the DNS query.

Whenever client makes a query, server identify the DNS. DNS (domain name server) query is used to identify the address of DNS.

After this, a TCP connection is to be established for further communication. TCP connection will be established by sending TCP SYN message.

After connection establishment, HTTP GET request to the server to retrieve the webpage it should display. After the server has sent the response, it closes the TCP connection.

36

A binary relation R on N × N is defined as follows: (a, b)R(c, d) if a ≤ c or b ≤ d. Consider the following propositions:

P: R is reflexive

Q: R is transitive

Which one of the following statements is TRUE?

  1. ((a))

    Both P and Q are true.

  2. ((b))

    P is true and Q is false.

  3. ((c))

    P is false and Q is true.

  4. ((d))

    Both P and Q are false.

Show Answer
Answer: ((b))

P is true and Q is false.

Concept:

Reflexive relation: Reflexive relation on a set is a binary element in which every element is related to itself. Let A be a set and R be the relation defined in it. R is set to be reflexive, if (a,a) ϵ R for all a ϵ A i.e. every element of A is related to itself.

Transitive relation: A binary relation R on a set A is transitive if whenever an element ‘a’ is related to an element ‘b’ and ‘b’ in turn is related to an element ‘c’, then a is also related to ‘c’.

For all, a, b, c ϵ A if aRb and bRc then aRc.

Explanation:

Here, it is given that:

(a, b)R(c, d) if a ≤ c or b ≤ d

Statement P: R is reflexive → TRUE

For R to be reflexive (a, b) R (a, b) should hold true.

Here, a ≤ a or b ≤ b

So, (a, b) R (a, b) holds true. R is reflexive.

Statement Q: R is transitive → FALSE

Consider the elements as (4, 5), (5, 1), (1, 1)

As, (4, 5) R (5, 1) so, 4 ≤ 5 or 5 ≤ 1

And (5, 1) R (1, 1) so, 1 ≤ 1

But here, (4, 5) R (1, 1) where, 4 ≥ 1 and 5 ≥ 1

For this, relation doesn’t hold true,

So, Relation R is not transitive.

37

Which one of the following well-formed formulae in predicate calculus is NOT valid?

  1. ((a))

    (∀x p(x) ⇒ ∀x q(x)) ⇒ (∃x ¬ p(x) ∨ ∀x q(x))

  2. ((b))

    (∃x p(x) ∨ ∃x q(x)) ⇒ ∃x (p(x) ∨ q(x)) 

  3. ((c))

    ∃x (p(x) ∧ q(x)) ⇒ (∃x p(x) ∧ ∃x q(x))

  4. ((d))

    ∀x (p(x) ∨ q(x)) ⇒ (∀x p(x) ∨ ∀x q(x))

Show Answer
Answer: ((d))

∀x (p(x) ∨ q(x)) ⇒ (∀x p(x) ∨ ∀x q(x))

Concept:

p ⇒ q means ¬p ∨ q

It means that p is true, and q is false, in that case this implication fails.

Explanation:

Consider, p(x) = x is a prime number

q(x) = x is a non-prime number

Option 1:

(∀x p(x) ⇒ ∀x q(x)) ⇒ (∃x ¬ p(x) ∨ ∀x q(x))   

In this, case after implication it becomes true and in case implication if there is true after implication then that predicate is valid. (∃x ¬ p(x) ∨ ∀x q(x)), this will become true by the example.

Option 2:

(∃x p(x) ∨ ∃x q(x)) ⇒ ∃x (p(x) ∨ q(x))   

This implication is also valid. In this, before implication it will become false. So, it is valid.

Option 3:

∃x (p(x) ∧ q(x)) ⇒ (∃x p(x) ∧ ∃x q(x))  

There exists a number x, which is both prime and non-prime which is false. A false statement can imply either true or false. So, it is valid.

Option 4:

∀x (p(x) ∨ q(x)) ⇒ (∀x p(x) ∨ ∀x q(x))  

Here, before implication, for all x, x is either prime or non-prime which is true.

After implication, for all x, x is prime or for all x, x is non-prime which is false. So, here a true statement implies a false statement which results in false. So, it is not valid.

38

Consider a set U of 23 different compounds in a Chemistry lab. There is a subset S of U of 9  compounds, each of which reacts with exactly 3 compounds of U. Consider the following statements: 

I. Each compound in U\S reacts with an odd number of compounds.

II. At least one compound in U\S reacts with an odd number of compounds.

III. Each compound in U\S reacts with an even number of compounds.

Which one of the above statements is ALWAYS TRUE?

  1. ((a))

    Only I

  2. ((b))

    Only II

  3. ((c))

    Only III

  4. ((d))

    None

Show Answer
Answer: ((b))

Only II

Here, it is given that U contains 23 different compounds i.e U= 23

S is the subset of U i.e. S= 9

U\S = 23 – 9 = 14

Consider this as a graph where U is the vertex set of graph G and S is the subset of vertices in G.

Now, it is given that S reacts with exactly 3 compounds of U. It means degree of every vertex is 3.

Sum of degree of every node of S = 9 × 3 = 27

U\S contains even number of compounds.

Statement I: Each compound in U\S reacts with an odd number of compounds.

Here, if each compound in U\S reacts with odd number of compounds, the sum of degree of all the nodes in U\S will be even and sum of degree of all nodes in graph G will be odd as sum of degree of all nodes in S is odd. This is not possible using handshaking lemma. So, Statement I is false.

Statement II: At least one compound in U\S reacts with an odd number of compounds.

To satisfy the handshaking lemma for graph, sum of degree of all nodes U\S must be odd. To make this happen, we require atleast one node of U\S with an odd degree. We can assign it in such a way that sum of degree of all nodes in U\S will be odd. So, it is true.

Statement III: Each compound in U\S reacts with an even number of compounds.

If each compound in U\S reacts with an even number of compounds, sum of degree of all nodes in U\S will become even and sum of degree of all nodes in graph will become odd as sum of degree of all nodes in S is odd. And an odd number added with an even number of results in an odd number. To satisfy the handshaking lemma, sum of degree of all nodes in the graph must be even. So, it is false.

39

The value of the expression 1399 (mod 17), in the range 0 to 16, is______.

40

Suppose the functions F and G can be computed in 5 and 3 nanoseconds by functional units UF and UG, respectively. Given two instances of UF and two instances of UG, it is required to implement the computation F(G(Xi)) for 1 ≤ I ≤ 10. Ignoring all other delays, the minimum time required to complete this computation is ______ nanoseconds.

41

Consider a processor with 64 registers and an instruction set of size twelve. Each instruction has five distinct fields, namely, opcode, two source register identifiers, one destination register identifier, and a twelve-bit immediate value. Each instruction must be stored in memory in a byte-aligned fashion. If a program has 100 instructions, the amount of memory (in bytes) consumed by the program text is ______. 

42

The width of the physical address on a machine is 40 bits. The width of the tag field in a 512 KB 8-way set associative cache is______ bits.

43

Consider a 3 GHz (gigahertz) processor with a three-stage pipeline and stage latencies τ1, τ2, and τ3 such that τ1 = 3τ2/4 = 2τ3. If the longest pipeline stage is split into two pipeline stages of equal latency, the new frequency is _______GHz, ignoring delays in the pipeline registers.

44

A complete binary min-heap is made by including each integer in [1,1023] exactly once. The depth of a node in the heap is the length of the path from the root of the heap to that node. Thus, the root is at depth 0. The maximum depth at which integer 9 can appear is_______. 

45

The following function computes XY for positive integers X and Y.

int exp(int X, int Y) {

            int res = 1, a = X, b = Y;

            while ( b != 0 ){

           if (b%2 == 0) {a = a*a; b = b/2; }

           else                 { res = res*a; b = b-1; }

           }

          return res;

Which one of the following conditions is TRUE before every iteration of the loop?

  1. ((a))

    XY = ab

  2. ((b))

    (resa)Y = (resX)b

  3. ((c))

    XY = res * ab

  4. ((d))

    XY = (res*a)b

Show Answer
Answer: ((c))

XY = res * ab

Consider X = 2, Y = 5,

Before iteration 1: res =1, a = 2, b = 5, X = 2, Y = 5

For these values all options are true.

After iteration 1 and before iteration 2:

if (b%2 == 0) {a = a*a; b = b/2;}

else                 { res = res*a; b = b-1; }                       // res = 2, b= 4

      }

So, res = 2, a= 2, b= 4, X = 2, Y = 5

After iteration 2 and before iteration 3:

if (b%2 == 0) {a = a*a; b = b/2;}                           // a = 4, b =4/2 =2

else                 { res = res*a; b = b-1; }                      

    }

Res = 2, a= 4, b= 2, X = 2, Y =5

After iteration 3 and before iteration 4:

if (b%2 == 0) {a = a*a; b = b/2;}                           // a = 16, b =2/2 = 1

else                 { res = res*a; b = b-1; }                      

   }

res = 2, a= 16, b = 1, X = 2, Y = 5

After iteration 4 and before iteration 5 :

 if (b%2 == 0) {a = a*a; b = b/2;}                          

else                 { res = res*a; b = b-1; }                       // res = 32, b = 0

}

After this, while condition becomes false

Before all these iterations, only option c will be true for these values, All other become false before iteration 2.

46

Consider the following New-order strategy for traversing a binary tree: 

  • Visit the root;
  • Visit the right subtree using New-order;
  • Visit the left subtree using New-order;
<br>

The New-order traversal of the expression tree corresponding to the reverse polish expression

3 4 * 5 – 2 ^ 6 7 * 1 + - is given by:

  1. ((a))
    • – 1 6 7 * 2 ^ 5 – 3 4 *
  2. ((b))

    – + 1 * 6 7 ^ 2 – 5 * 3 4

  3. ((c))

    – + 1 * 7 6 ^ 2 – 5 * 4 3

  4. ((d))

    1 7 6 * + 2 5 4 3 * – ^ –

Show Answer
Answer: ((c))

– + 1 * 7 6 ^ 2 – 5 * 4 3

In case of reverse polish notation, we follow the:

  1. visit left subtree

  2. visit right subtree

  3. visit root

New order strategy is given as:

  1. visit root

  2. visit right subtree

  3. visit left subtree

It is the reverse of reverse- polish notation.

So, for finding the new order traversal of given reverse polish notation just reverse that:

Reverse polish traversal: 3 4 * 5 – 2 ^ 6 7 * 1 + -

New order traversal:  – + 1 * 7 6 ^ 2 – 5 * 4 3

Alternate solution:

Convert the given reverse polish notation in IN- order

3 4 * 5 – 2 ^ 6 7 * 1 + -

(3 * 4) 5 – 2 ^ 6 7 * 1 + -

((3*4) - 5) 2 ^ 6 7 * 1 + -

(((3*4) - 5)^ 2) 6 7 * 1 + -

(((3*4) - 5)^ 2) (6 * 7) 1 + -

(((3*4) - 5)^ 2) ((6 * 7) + 1)

(((3*4) - 5)^ 2) - ((6 * 7) + 1)

Now, from this inorder traversal, find the new order traversal;

(((3*4) - 5)^ 2) - ((6 * 7) + 1)

  • ((6 * 7) + 1) (((3*4) - 5)^ 2)
    • 1 (6 * 7) (((3*4) - 5)^ 2)
    • 1 * 7 6 (((3*4) - 5)^ 2)
    • 1 * 7 6 ^ 2 ((3*4) - 5)
    • 1 * 7 6 ^ 2 - 5 (3*4)
    • 1 * 7 6 ^ 2 - 5 * 4 3

Hence option 3 is correct.

47

Consider the following program:

int f(int *p, int n)

{

             if(n <= 1) return 0;

             else return max (f(p + 1, n – 1), p[0] – p[1]);

}

int main()

{

int a[ ] = {3, 5, 2, 6, 4};

printf("%d", f(a,5));

}

Note: max(x, y) returns the maximum of x and y.

The value printed by this program is

48

Let A1, A2, A3, and A4 be four matrices of dimensions 10 × 5, 5 × 20, 20 × 10, and 10 × 5, respectively. The minimum number of scalar multiplications required to find the product A1A2A3A4 using the basic matrix multiplication method is ______.

49

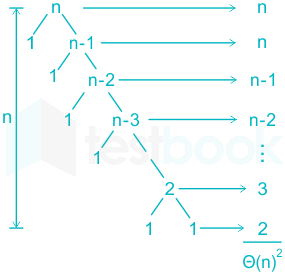
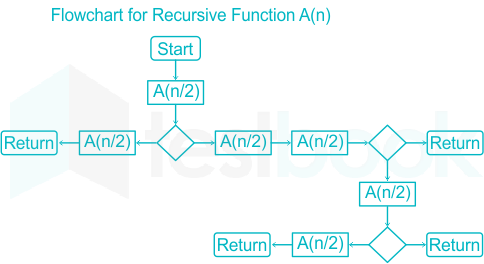
The given diagram shows the flowchart for a recursive function A(n). Assume that all statements, except for the recursive calls, have O(1) time complexity. If the worst-case time complexity of this function is O(nα), then the least possible (accurate up to two decimal position) of α is _______.

50

The number of ways in which the numbers 1, 2, 3, 4, 5, 6, 7 can be inserted in an empty binary search tree, such that the resulting tree has height 6, is.

Note: The height of a tree with a single node is 0.

51

In an adjacency list representation of an undirected simple graph G = (V, E), each edge (u, v) has two adjacency list entries: [v] in the adjacency list of u, and [u] in the adjacency list of v. These are called twins of each other. A twin pointer is a pointer from an adjacency list entry to its twin. If |E| = m and |V| = n, and the memory size is not a constraint, what is the time complexity of the most efficient algorithm to set the twin pointer in each entry in each adjacency list?

  1. ((a))

    Θ(n2)

  2. ((b))

    Θ(n + m)

  3. ((c))

    Θ(m2)

  4. ((d))

    Θ(n4)

Show Answer
Answer: ((b))

Θ(n + m)

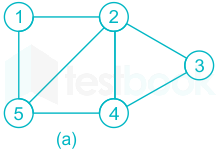
We perform a BFS here. Suppose 1 is adjacent to 2 hence 2 is also adjacent to 1, in adjacency list we create one node in linked list for a vertex if it is adjacent. So, 1 and 2 are twins. Linked list of 1 will have entry for 2 and linked list of 2 will have entry for 1. In this way, we can have pointers for all twins in O (m + n) time. Level order traversal is required here.

Graph:

Adjacency list:

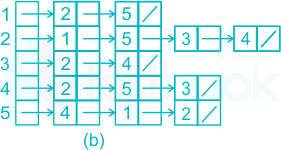
Also, extra field is there for storing number of linked lists for each vertex which is extra space. (But here memory size is not a constraint).

Overall time complexity to set the twin pointer in each entry in adjacency list is O(m + n).

52

Consider the following two statements:

I. If all states of an NFA are accepting states then the language accepted by the NFA is ∑*.

II. There exists a regular language A such that for all languages B, A ∩ B is regular.

Which one of the following is CORRECT?

  1. ((a))

    Only I is true

  2. ((b))

    Only II is true

  3. ((c))

    Both I and II are true

  4. ((d))

    Both I and II are false

Show Answer
Answer: ((b))

Only II is true

Statement I:

If all states of an NFA are accepting states, then the language accepted by the NFA is ∑*. (FALSE)

If we have an NFA with one state and on it, we did not define any transition then it accepts only null not ∑*.

Also, while converting an NFA to DFA, a dead state may be there. So even though all the final states of DFA have all transition, a few transitions may go to a dead state. Hence, that string will not be accepted.

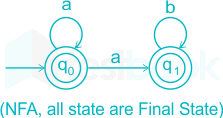
If the string is b then is not accepted by the given NFA and b ⊂ ∑*

Here, in this, it is not accepting string b or strings that start with b. So, it is not accepting ∑*.

Statement II:

There exists a regular language A such that for all languages B, A ∩ B is regular. (TRUE)

There exists a regular language A= Ø, such that Ø ∩ B = Ø which is a regular language.

So, this statement is true.

53

Consider the following languages:

L1 = {anbmcn + m: m, n ≥ 1}

L2 = {anbnc2n: n ≥ 1}

Which one of the following is TRUE?

  1. ((a))

    Both L1 and L2 are context-free

  2. ((b))

    L1 is context-free while L2 is not context-free

  3. ((c))

    L2 is context-free while L1 is not context-free

  4. ((d))

    Neither L1 nor L2 is context-free

Show Answer
Answer: ((b))

L1 is context-free while L2 is not context-free

Statement I: L1 = {an bm cn + m: m, n ≥ 1}

L1 can be accepted easily by single stack. First, push a’s into stack, then push b’s into stack then read c’s and pop b’s, when no b’s left on stack, then keep reading c’s and pop a’s. When no c’s left in input and stack is empty then accepted by only one stack. Hence L1 is a context free language.

Statement II: L2 = {anbnc2n: n ≥ 1}

This language can’t be accepted by a single stack. When we push a’s into stack and pop them with b’s then it satisfies number of a’s = number of b’s but we left with empty stack and c’s in input. We can’t ensure that number of c’s are double than a and b’s. A push down automata can’t remember number of a’s for third set of characters, that is. c.

Hence L2 is a context sensitive language but not context free language.

54

Consider the following languages.

L1 = { <M> | M takes at least 2016 steps on some input},

L2 = { <M> | M takes at least 2016 steps on all inputs} and

L3 = { <M> | M accepts ϵ},

Where for each Turing machine M, denotes a specific encoding of M. Which one of the following is TRUE?

  1. ((a))

    L1 is recursive and L2, L3 are not recursive

  2. ((b))

    L2 is recursive and L1, L3 are not recursive

  3. ((c))

    L1, L2 are recursive and L3 is not recursive

  4. ((d))

    L1, L2, L3 are recursive

Show Answer
Answer: ((c))

L1, L2 are recursive and L3 is not recursive

Statement I:

L1 = { <M> | M takes at least 2016 steps on some input},

This language is decidable, because counting number of steps can always be decided. We can find TM whether it takes more than 2016 steps on some input string which has length up to 2016. If it processes 2016 steps till end, then will take at least 2016 steps. But if these are not taking 2016 steps, it means these have taken at most 2015 steps which means string is not processed completely. Also, if Turing machine reaches the halt state before reaching the end of string of input, it can be decided. In all cases, Turing machine M is recursive.

Statement II:

L2 = { <M> | M takes at least 2016 steps on all inputs}

For this, consider M makes less than 2016 steps for some input and we can just give it all possible inputs of length less than 2016 steps and check if it can reach a halt state within 2016 steps. All the possible strings make a finite set. Thus, accepted by Turing machine. Hence, it is recursive language.

Statement III:

L3 = { <M> | M accepts ϵ},

It is based on the concept of rice theorem i.e. any non - trivial property of the language recognizable by a Turing machine is undecidable. As this language contains ϵ which is non – trivial property of recursive enumerable language and hence undecidable. Hence, it is not recursive.

55

Which one of the following grammars is free from left recursion?

  1. ((a))

    S → AB

    A → Aa | b

    B → c

  2. ((b))

    S → Ab | Bb | c

    A → Bd | ϵ

    B → e

  3. ((c))

    S → Aa | B

    A → Bb | Sc | ϵ

    B → d

  4. ((d))

    S → Aa | Bb | c

    A → Bd | ϵ

    B → Ae | ϵ

Show Answer
Answer: ((b))

S → Ab | Bb | c

A → Bd | ϵ

B → e

Method: By option elimination

Option 1:

S → AB

A → Aa | b

B → c

Here, there is a left recursion in “A → Aa”

Option 3:

S → Aa | B

A → Bb | Sc | ϵ

B → d

Since, S → Aa and A → Sc which will result in S → Sca

So, it results in a left recursion.

Option 4:

S → Aa | Bb | c

A → Bd | ϵ

B → Ae | ϵ

Since A → Bd and B → Ae

which results in left recursion, A → Aed or B → Bde

Option 2:

S → Ab | Bb | c

A → Bd | ϵ

B → e

This grammar doesn’t include direct left recursive statement or indirect left recursive statement production.

56

A student wrote two context-free grammars G1 and G2 for generating a single C-like array declaration. The dimension of the array is at least one. For example,

int a[10] [3] ;

The grammars use D as the start symbol, and use six terminal symbols int; id[ ] num

Grammar G1Grammar G2
D → int L;D → int L;
L → id[EL → idE
E → num]E → E[num]
E → num][EE → [num]


Which of the grammars correctly generate the declaration mentioned above?

  1. ((a))

    Both G1 and G2

  2. ((b))

    Only G1

  3. ((c))

    Only G2

  4. ((d))

    Neither G1 nor G2

Show Answer
Answer: ((a))

Both G1 and G2

Grammar G1 is:

D → int L;

L → id [E

E → num]

E → num] [E

Generate one dimensional array: a[10]

D → int L

int id[E

int id[num]

This leads to int a[10]

Generate two-dimensional array: int a [10] [3];

D → int L;

int id [E;

int id [num] [E;

int id [num] [num];

This leads to int a[10][3]

It correctly generates declaration given.

Grammar G2 is:

D → int L;

L → idE

E → E[num]

E → [num]

Generate one dimensional array: a[10]

D → int L;

int idE

int id[num]

This leads to int a[10]

Generate two-dimensional array: int a [10] [3];

int a[10][3];

D → int L;

int id E;

int id E[num];

int id [num] [num];

This leads to int a[10][3]

So, both grammar G1 and G2 generates the given declaration.

57

Consider the following processes, with the arrival time and the length of the CPU burst given in milliseconds. The scheduling algorithm used is pre-emptive shortest remaining-time first. 

ProcessArrival TimeBurst Time
P1010
P236
P371
P483


The average turn-around time of these processes is_______ milliseconds.

58

Consider the following two-process synchronization solution.

Process 0 - - - - - - - - Entry: loop while (turn == 1); (critical section) Exit: turn = 1;Process 1 - - - - - - - - Entry: loop while (turn == 0); (critical section) Exit: turn = 0;


The shared variable turn is initialized to zero. Which one of the following is TRUE?

  1. ((a))

    This is a correct two-process synchronization solution.

  2. ((b))

    This solution violates mutual exclusion requirement.

  3. ((c))

    This solution violates progress requirement.

  4. ((d))

    This solution violates bounded wait requirement.

Show Answer
Answer: ((c))

This solution violates progress requirement.

Concept:

Mutual exclusion: Mutual exclusion prevents simultaneous access to a shared resource.

Progress: If no process is executing in critical section and other processes are waiting outside the critical section then only those processes that are not executing in their remainder section can participate in deciding which will enter in the critical section next and selection cannot be postponed.

Bounded wait: A bound must exist on the number of times that other processes are allowed to enter their critical sections after a process has made a request to enter its critical section and before that request is granted.

Explanation:

There is strict alteration here i.e. after completion of process 0 if it wants to start again, it will have to wait until process leaves the critical section.

This violates the progress requirement.

As there are only two processes involved, it means there exists a bound on the number of times other processes are allowed to enter its critical section. So, it satisfies the bounded waiting.

Also, there is a mutual exclusion in this because only one process can enter the critical section at a time.

59

Consider a non-negative counting semaphore S. The operation P(S) decrements S, and V(S) increments S. During an execution, 20 P(S) operations and 12 V(S) operations are issued in some order. The largest initial value of S for which at least one P(S) operation will remain blocked is_______.

60

A file system uses an in-memory cache to cache disk blocks. The miss rate of the cache is shown in the figure. The latency to read a block from the cache is 1 ms and to read a block from the disk is 10 ms. Assume that the cost of checking whether a block exists in the cache is negligible. Available cache sizes are in multiples of 10 MB.

The smallest cache size required to ensure an average read latency of less than 6 ms is ______ MB.

61

Consider the following database schedule with two transactions, T1 and T2.

S = r2(X); r1 (X); r2(Y); w1(X); r1 (Y); w2(X); a1; a2

where ri(Z) denotes a read operation by transaction Ti on a variable Z, wi(Z) denotes a write operation by Ti on a variable Z and ai denotes an abort by transaction Ti.

Which one of the following statements about the above schedule is TRUE?

  1. ((a))

    S is non-recoverable

  2. ((b))

    S is recoverable, but has a cascading abort

  3. ((c))

    S does not have a cascading abort

  4. ((d))

    S is strict

Show Answer
Answer: ((c))

S does not have a cascading abort

Concept:

Cascadeless schedule

It is one in which each pair of transaction Ti and Tj such that Tj reads the data that is written by Ti than the commit or abort operation of Ti should appear before the read operation of Tj

T1T2
r(x)
r(x)
r(y)
w(x)
r(y)
w(x)
abort(a)
abort(a)


Since there are no write-in T1 read by T2. Hence S is cascadeless schedule, that is, S does not have a cascading abort

62

Consider the following database table named water_schemes:

Water_schemes
Scheme_noDistrict_nameCapacity
1Ajmer20
1Bikaner10
2Bikaner10
3Bikaner20
1Churu10
2Churu20
1Dungargarh10


The number of tuples returned by the following SQL query is ______.

with total (name, capacity) as

            select district_name, sum(capacity)

            from water_schemes

            group by district_name

with total_avg (capacity) as

            select avg (capacity)

from total

select name

            from total, total_avg

            where total.capacity ≥ total_avg.capacity

63

A network has a data transmission bandwidth of 20 × 106 bits per second. It uses CSMA/CD in the MAC layer. The maximum signal propagation time from one node to another node is 40 microseconds. The minimum size of a frame in the network is ______bytes.

64

For the IEEE 802.11 MAC protocol for wireless communication, which of the following statements is/are TRUE?

I. At least three non-overlapping channels are available for transmissions.

II. The RTS-CTS mechanism is used for collision detection.

III. Unicast frames are ACKed.

  1. ((a))

    All I, II, and III

  2. ((b))

    I and III only

  3. ((c))

    II and III only

  4. ((d))

    II only

Show Answer
Answer: ((b))

I and III only

IEEE 802.11 MAC is wi-fi

Statement I. At least three non-overlapping channels are available for transmissions.

802.11 operates in the frequency range of 2.4 GHz to 2.485 GHz. Within this 85 MHZ band, 802.11 defines 11 partially overlapping channels. Any two channels are non-overlapping if they are separated by four or more channels. In particular the set of channels 1, 6, and 11 is the only set of three non-overlapping channels. This statement is true.

Statement II. The RTS-CTS mechanism is used for collision detection.

RTS (request to send) and CTS (control to send) are the control frames. They are not used for collision detection. They just help in collision reduction. RTS-CTS are used to announce to all nodes, that for which node wireless channel is reserved for communication. So, given statement is false.

Statement III. Unicast frames are ACKed.

Because there is no way to detect collision in wireless, an ACK must be sent after each unicast frame transmission. If no ACK is sent, then there is no way to know if a previously sent transmission arrived to its destination so it will be resent. So, given statement is true.

65

Consider 128 × 103 bits/second satellite communication link with one way propagation delay of 150 milliseconds. Selective retransmission (repeat) protocol is used on this link to send data with a frame size of 1 kilobyte. Neglect the transmission time of acknowledgement. The minimum number of bits required for the sequence number field to achieve 100% utilization is _______.

Attempt this paper under real exam conditions

Timed interface, section switching, instant scoring, and question-by-question analytics — free.

Start Timed Attempt